

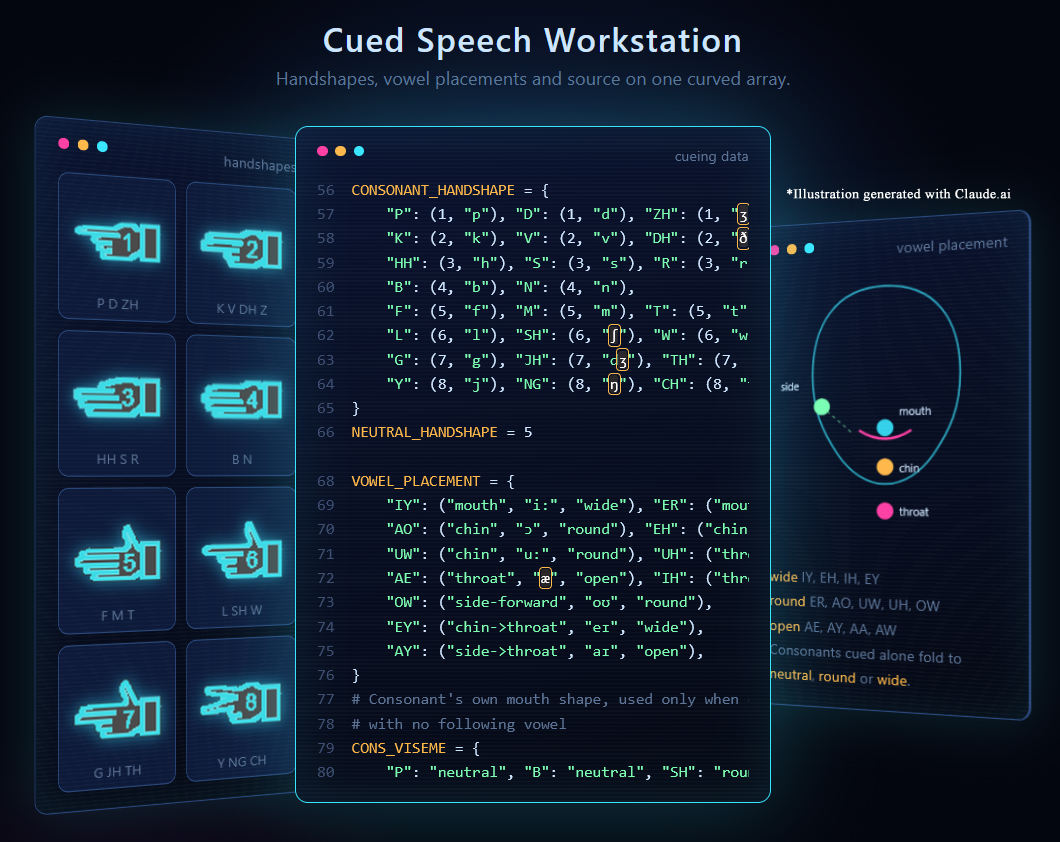
We are designing a proof of concept to show how Cued Speech can be formalized and implemented in code. The core script will become part of the CUESPECS platform. In parallel, we are designing the alpha release as a standalone learning tool.
Why?
Learners benefit from interactive educational materials.
How?
The code converts graphemes to phonemes, that is, English text to sound units. The phonemes are then mapped onto cuems, which are the visible product of cueing in Cued Speech. In a nutshell, the cuems transform sound-based English into vision-based English in a way that is unambiguous, unlike lip reading alone. Our code handles each cuem as a combination of mouth shape, handshape, and hand placement. These so-called visemes and kinemes are finally mapped onto a digital cue card for each cuem. Taken together, the output visualizes Cued Speech step by step for any sentence the user enters.
When?
This is the very beginning of our pipeline. We are excited about the headway we are making and could not wait to share a first look.
Question!
Let us know in the comments:
A. if you would like to see a raw build as soon as possible, or
B. if you would prefer a polished version down the road.
–Cheers from the Devs!